Mistral speech-to-text pod crashes with segmentation fault after codec removal
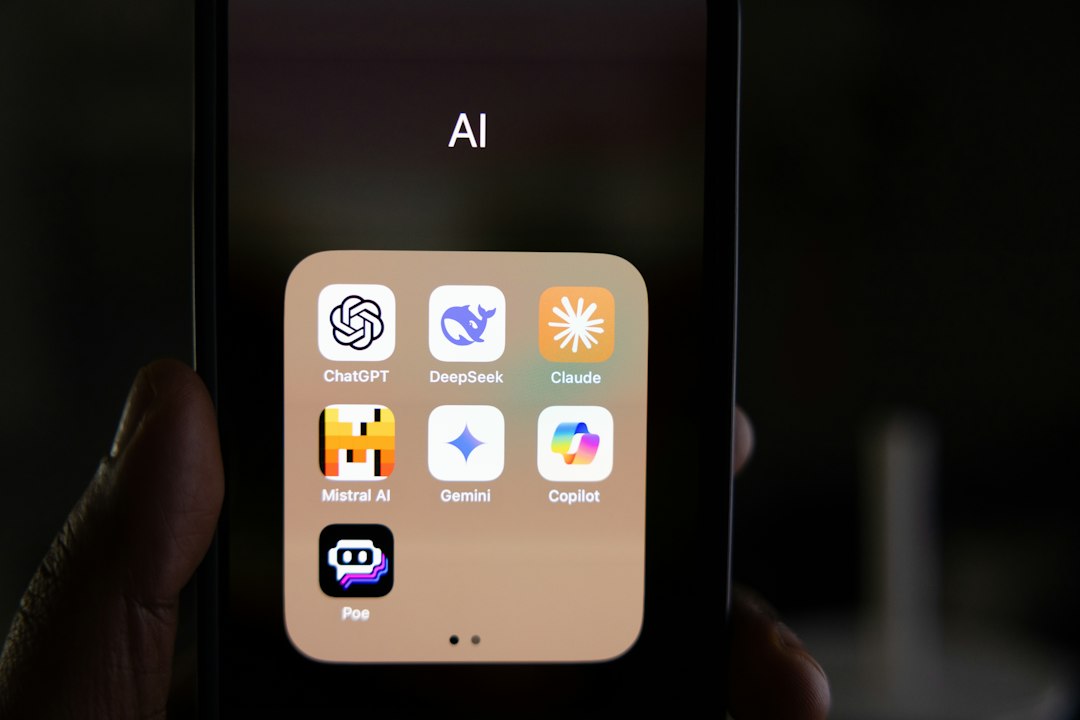
A person holding a smart phone in their hand

Mistral speech‑to‑text pod crashes with segmentation fault after codec removal Problem The mistral-stt StatefulSet runs on GPU‑enabled nodes (Kubernetes v1.27). After a routine image update that removed unused audio codec packages, the pod starts but crashes during the first inference request. The container logs end with a segmentation fault (SIGSEGV) inside the audio preprocessing library. … Read more
OAuth2 token request timeout in Kubernetes pods after Docker restart

chart

Problem – OAuth2 Token Request Timeout After Docker Restart After a Docker daemon restart on a node, pods that host the AI inference service begin to fail during the OAuth2 token acquisition phase. The service logs show repeated timeouts when contacting the authorization server, and the authentication flow aborts, causing inference requests to return 401 … Read more

Mistral inference pod evictions during multi-region replication sync

an iphone sitting on top of a table next to a leaf

Problem – Mistral Inference Pods Evicted During Multi‑Region Replication Sync The Mistral AI inference service runs as a set of Deployment pods behind a ClusterIP service. When a multi‑region replication job (running as a CronJob that streams model checkpoints from the primary region to secondary regions) starts, operators observe a spike in pod evictions: Warning … Read more

Pinecone pods ErrImagePull after Helm upgrade on GKE

brown pine cone on green grass during daytime

Problem: Pinecone pods stuck in ErrImagePull after a Helm upgrade on GKE After upgrading the pinecone Helm release on a Google Kubernetes Engine (GKE) cluster, the newly‑created pods enter the ErrImagePull / ImagePullBackOff state. Typical pod description output looks like: $ kubectl describe pod pinecone-0 … Events: Type Reason Age From Message —- —— —- —- … Read more

Kubernetes NetworkPolicy blocking model-serving pods from Redis cache

a group of blue boxes

Problem – Model‑Serving Pods Cannot Reach Redis Cache In a production Kubernetes cluster the AI inference workloads run in the model-serving namespace. The Redis cache that stores model artifacts lives in the data-services namespace and is exposed via the Service redis-data-services (port 6379). After a recent deployment of a default‑deny NetworkPolicy in model-serving, inference requests … Read more

Admission controller rejection of GPT-4 pod missing securityContext in canary

a laptop computer sitting on top of a wooden table

Problem – Admission Controller Rejects GPT‑4 Canary Pods During a staged rollout of a new GPT‑4 inference service, the canary pods never reach the Running state. The Kubernetes API server returns a 403 error from the pod-security-admission webhook and a custom model‑policy webhook. Typical log excerpts look like: Error from server (Forbidden): admission webhook “pod-security-admission” … Read more

Google Gemini pods pending despite free A100/H100 GPUs in Kubernetes

a close up of a cell phone with buttons

Problem: Gemini Training Pods Remain Pending Despite Free A100/H100 GPUs In a production Vertex AI cluster that mixes NVIDIA A100 and H100 nodes, engineers observed that new gemini training pods never transition to Running. The scheduler reports: FailedScheduling: 0/6 nodes are available: 6 Insufficient nvidia.com/gpu. Other observed symptoms include: Pod events showing pod didn’t match … Read more

PostgreSQL index rebuild lock timeout after Kubernetes pod restart

Rows of black server racks with white logos in a data center

Problem Description During rolling restarts or horizontal pod autoscaling of a PostgreSQL StatefulSet, repeated REINDEX CONCURRENTLY operations abort with lock timeouts or out‑of‑memory errors. The symptoms observed in production are: Log entries such as: 2024-07-12 14:03:21.123 UTC [12345] LOG: index build (concurrently) aborted: could not obtain exclusive lock on relation “orders_pkey” 2024-07-12 14:03:21.124 UTC [12345] … Read more

Pod eviction under memory pressure during large model evaluation on Azure

icon

Problem: Pods Evicted Under Memory Pressure During Large‑Scale Model Evaluation on Azure During batch evaluation of transformer‑based models (12‑20 GB checkpoint size) on Azure virtual machines managed by AKS, operators observed repeated pod evictions: Events: Type Reason Age From Message —- —— —- —- ——- Normal Killing 5m kubelet Killing container with id docker://evaluator:Need to kill … Read more

Kubernetes pod crash loop after canary deploying Hugging Face Transformers model

A white robot car toy with blue and red stripes

Problem Description A canary rollout of a Hugging Face transformers model on a Kubernetes cluster results in the newly created pods entering CrashLoopBackOff. The failure manifests during the model initialization phase, before the inference server becomes ready. Typical log excerpts include: 2024-08-30T12:15:42.123Z ERROR [model_loader] RuntimeError: CUDA out of memory. Tried to allocate 12.34 GiB. This … Read more